- Page d'accueil /
- Livres /
- Ordinateurs et technologie /
- Programming /
- Software Design, Testing & Engineering /
- Software Development /
- Learning Spark: Lightning-Fast Big Data Analy...
0 ratings


Numéro d'article:
232567
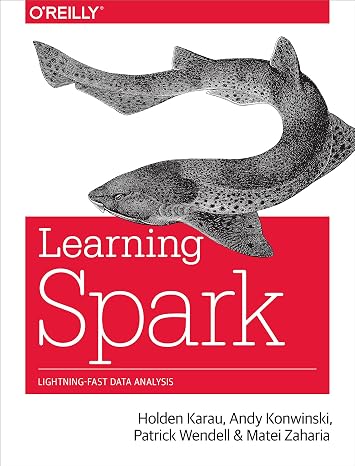
Learning Spark: Lightning-Fast Big Data Analysis
90% des répondants recommanderaient ceci à un ami
Numéro d'article:
232567
€ 26
Détails du prix
Hors frais de livraison et de douane ( Les frais de livraison et de douane seront calculés lors du paiement )
*Tous les articles seront importés depuis États-Unis
0 ratings
Écrire un commentaire
En stock
 Importé depuis la boutique USA
QTY:
Commandez maintenant et recevez votre commande aux alentours du Jeudi, Octobre 15
Transaction sécurisée
Ubuy s'engage à protéger votre sécurité et votre confidentialité. Notre système avancé de sécurité des paiements garantit la confidentialité en chiffrant vos informations lors de la transmission grâce aux protocoles AES (Advanced Encryption Standards) et SSL (Secure Socket Layer). Vos coordonnées de paiement sont 100 % sécurisées car nous ne partageons pas vos informations de paiement avec des vendeurs tiers.
Nos meilleurs partenaires logistiques


Data in all domains is getting bigger. How can you work with it efficiently? This book introduces Apache Spark, the open source cluster computing system that makes data analytics fast to write and fast to run.

Livraison
rapide

Retour
gratuit*

Emballage sécurisé

Produits 100 % originaux

Conformité PCI DSS

Certifié ISO 27001
Note: Step Down Voltage Transformer required for using electronics products of États-Unis store (110-120). Recommended power converters Acheter maintenant.


Ce qui se démarque
Real-Time Processing
Empowers users to analyze big data streams in real-time, offering immediate insights and responsive analytics unmatched in speed compared to traditional tools.
User-Friendly Interface
Designed for accessibility, making complex big data analytics understandable for both novice and experienced users, thus broadening its appeal across diverse skill levels.
Comprehensive Learning
Covers foundational concepts and advanced techniques in big data analysis, ensuring readers are well-equipped to utilize Spark effectively in real-world applications.
Détails du produit
| Publisher | O'Reilly Media |
| Publication date | March 24, 2015 |
| Edition | 1st |
| Language | English |
| Print length | 274 pages |
| ISBN-10 | 1449358624 |
| ISBN-13 | 978-1449358624 |
| Item Weight | 1.05 pounds (480 grams) |
| Dimensions | 7 x 0.63 x 9.19 inches (17.8 x 1.6 x 23.3 cm) |
À qui est-ce destiné ?

-
Data Engineers
Ideal for data engineers looking to master Spark for efficient big data processing and transformation tasks.
-
Data Scientists
Beneficial for data scientists wanting to leverage Spark for large-scale data analysis and machine learning applications.
-
Big Data Analysts
Great for analysts delving into big data techniques and seeking to enhance their analytical workflows with Spark.

-
Beginners
Not well-suited for absolute beginners who lack prior knowledge of data processing or programming concepts.
DESCRIPTION DU PRODUIT
Learning Spark: Lightning-Fast Big Data Analysis
Vous avez une question ? Chattez avec nous
Questions et réponses des clients
-
question:
What topics are covered in Learning Spark: Lightning-Fast Big Data Analysis?
répondre: Learning Spark covers a wide range of topics essential for Big Data analysis, including core concepts of Apache Spark, the architecture of Spark, data processing with RDDs (Resilient Distributed Datasets), and DataFrames. It also dives into Spark SQL, machine learning with MLlib, and streaming data. These topics equip readers with both practical skills and theoretical foundations, making it useful for data engineers, data scientists, and software developers looking to optimize data processing workflows in their projects. -
question:
Who is the target audience for Learning Spark?
répondre: The book is primarily aimed at data engineers, data scientists, and software developers who want to leverage the power of Apache Spark for Big Data processing. It’s suitable for individuals who have a basic understanding of data processing concepts and are looking to advance their knowledge of distributed data processing systems. Therefore, readers such as university students, industry professionals, and tech enthusiasts will find this book valuable for improving their data analysis skills. -
question:
How does Learning Spark help in understanding Apache Spark?
répondre: Learning Spark provides a comprehensive guide to understanding Apache Spark through practical examples and real-world applications. Each chapter is designed to build on previous knowledge, reinforcing key concepts with hands-on coding exercises. This approach not only helps deepen understanding but also facilitates better retention of the material. For instance, data practitioners can apply what they learn to their everyday work, whether it be in data cleaning, processing, or machine learning tasks. -
question:
What are RDDs and why are they important in Spark?
répondre: RDDs, or Resilient Distributed Datasets, are a fundamental data structure in Apache Spark that enable distributed data processing. They are immutable collections of objects that can be processed in parallel across a cluster, allowing for fault tolerance and efficient data manipulation. Understanding RDDs is crucial because they form the basis for most operations in Spark, enabling data engineers to perform complex transformations and actions on large datasets swiftly and effectively. -
question:
Can Learning Spark be used for beginners in Big Data?
répondre: Yes, Learning Spark is also suitable for beginners. The authors start with fundamental concepts of Spark and gradually introduce more advanced topics. Each chapter includes practical examples to illustrate how Spark can be applied in real-world scenarios. Beginners can benefit from this structured approach, making it easier to grasp complex notions of Big Data processing while providing a solid foundation for further learning. -
question:
What kind of practical examples does Learning Spark include?
répondre: The book includes various practical examples that illustrate key Spark concepts. For example, it covers hands-on projects involving data ingestion, cleaning, and analysis, allowing readers to see how Spark can be used in actual applications. These case studies enable readers to bridge the gap between theory and practice, giving them immediate insights into how to apply Spark in tasks like batch processing and real-time data analytics. -
question:
Is there a discussion about machine learning in Learning Spark?
répondre: Indeed, Learning Spark includes a section dedicated to machine learning using Spark's MLlib. This part of the book explains the principles behind machine learning algorithms, how they are implemented in Spark, and real-world applications. Readers will learn to build machine learning models that can handle massive datasets, equipping them with the knowledge to integrate machine learning into their data processing workflows effectively. -
question:
How does Learning Spark approach data streaming?
répondre: Learning Spark takes a practical approach to data streaming by introducing Spark Streaming. The book describes how to handle real-time data ingestion and processing, enabling readers to build applications that respond to data as it is produced. This feature is crucial for environments requiring immediate insights, like financial analytics or social media monitoring, empowering readers to harness streaming capabilities alongside batch processing in their projects. -
question:
Where can I buy Learning Spark: Lightning-Fast Big Data Analysis 1st Edition in Monaco?
répondre: You can buy Learning Spark: Lightning-Fast Big Data Analysis 1st Edition on Ubuy. Ubuy offers a straightforward purchasing process, often featuring a wide range of books and resources tailored to meet the needs of readers in Monaco. Their platform is designed to make it easy to find and acquire products, ensuring you can access this vital resource in your journey to mastering Big Data analysis with Apache Spark. -
question:
What makes Learning Spark a recommended resource over other Big Data books?
répondre: Learning Spark stands out because it offers a deep dive into the practical aspects of Apache Spark, combining theoretical explanations with hands-on coding examples. The authors are renowned experts in the field, making the content not only informative but also authoritative. Additionally, the clear structure and flow make it more accessible than many other complex Big Data books, providing readers with an engaging and effective learning experience.
Software Development Editorial Review
**Editorial Review of *Learning Spark: Lightning-Fast Big Data Analysis*** *Learning Spark* serves as an essential primer for anyone looking to delve into the world of Apache Spark, particularly those who may not have extensive programming experience. Customers have found it to be approachable and well-structured, allowing them to grasp foundational principles while also providing insights into more advanced topics. The authors, recognized developers of Spark, lend significant credibility to the content, crafting a narrative that is both informative and accessible. Readers appreciate the thoroughness of the text, noting that it Consolidates a wealth of information that might otherwise be scattered across numerous online resources. The book effectively covers core Spark concepts and reviews its functionalities across Scala, Python, and Java, highlighting their respective strengths and shortcomings in the Spark ecosystem. This multi-lingual approach has resonated with readers, making it easier for them to relate to the examples provided. However, the book is not without its criticisms. Some readers have noted that the presentation of code examples leaves much to be desired, with a lack of self-containment making them difficult to implement in a standalone manner. This issue is compounded by the rapid evolution of Spark, which can render some examples out-of-date or divergent from current best practices. Despite these drawbacks, many assert that *Learning Spark* still offers Considerable value, especially for beginners or those refreshing their knowledge, even if they ultimately recommend supplementary texts for a more advanced exploration of the subject. While the introductory chapters were well-received, specific sections like Spark Streaming were viewed as less accessible, creating a mixed experience throughout the book. Nonetheless, the clarity of writing and the well-organized structure provide a solid foundation for readers to explore Spark further. In conclusion, *Learning Spark* is lauded as a thoughtful resource for acquiring a practical understanding of big data analysis through Spark, albeit with caveats regarding the execution of code examples. Readers are encouraged to approach it as a starter guide, before potentially advancing to more comprehensive references. **
Avis et évaluations clients
1 évaluations des clients
-
5 étoile
100%
-
4 étoile
0%
-
3 étoile
0%
-
2 étoile
0%
-
1 étoile
0%
Donnez votre avis sur ce produit
Partagez votre avis avec d'autres clients
Avantages
- Clear and accessible introduction to Spark
- Strong foundational principles for beginners
- Multi-lingual examples in Scala, Python, and Java
- Concise and informative writing style
Les inconvénients
- Code examples can be difficult to implement
CONFIANCE EN LA PLATEFORME & PROTECTION DE L'ACHETEUR
JK
Jasmin
Acheteur vérifié
“Great products and very good service: very easy and very fast international delivery.”
9 September 2026 · via Trustpilot
AG
Anke
Acheteur vérifié
“Wonderful online shopping experience, smooth transaction from the start. Payment method works conveniently and delivery is unexpectedly fast and reliable. You go the extra mile for service. What makes this even more amazing, you deliver to Namibia. I will remain a happy Ubuy customer and will increase my purchases for sure! Thank you!”
10 September 2026 · via Trustpilot
H
Hazel
Acheteur vérifié
“Very easy to find the products what you need, and so fast delivery, that’s why I highly recommended to others costumers to used ubuy.”
10 September 2026 · via Trustpilot
O
Opaleye
Acheteur vérifié
“I received exactly what I ordered I was skeptical about your site because that was my first time to order. But the order came timely and neatly packaged. I was not disappointed. Thank you.”
11 September 2026 · via Trustpilot
AC
Adele
Acheteur vérifié
“Easy to find and order what you want on the website. Delivery is quick to the UK”
8 September 2026 · via Trustpilot
Paiement sécurisé
Global Delivery
Retours faciles
Genuine Products
Historique des prix du produit
Informations importantes
- Limitations : Pour les produits expédiés à l'international, veuillez noter que toute garantie du fabricant peut ne pas être valide ; les options de service du fabricant peuvent ne pas être disponibles ; les manuels, instructions et avertissements de sécurité des produits peuvent ne pas être dans les langues du pays de destination ; les produits (et les matériaux qui les accompagnent) peuvent ne pas être conçus conformément aux normes, spécifications et exigences d'étiquetage du pays de destination ; et les produits peuvent ne pas être conformes à la tension et aux autres normes électriques du pays de destination (nécessitant l'utilisation d'un adaptateur ou d'un convertisseur le cas échéant). Il incombe au destinataire de s'assurer que le produit peut être importé légalement dans le pays de destination. En cas de commande auprès d'Ubuy ou de ses filiales, le destinataire est l'importateur officiel et doit se conformer à toutes les lois et réglementations du pays de destination.
- Tous les produits listés sur Ubuy ne sont pas à vendre, Ubuy étant un moteur de recherche mondial. Les produits sont soumis aux réglementations en matière d'exportation et de commerce.
€ 26
Commandez maintenant et recevez votre commande aux alentours du Jeudi, Octobre 15
This item is not restrict in my country.(Please click on above link if this item is not restrict in your country, So our team will review and allow.)
QTY:
Transaction sécurisée
Conforme PCI DSS et certifié ISO 27001:2022, avec des paiements chiffrés et une protection complète de l'acheteur pour chaque commande.
Nos meilleurs partenaires logistiques
Livraison transfrontalière la plus rapide
Caractéristiques et avantages
- Introduces Apache Spark for lightning-fast data analytics
- Tackles big datasets quickly through simple APIs in Python, Java, and Scala
- Includes new information on Spark SQL, Spark Streaming, setup, and Maven coordinates
- Written by the developers of Spark, ensuring quick setup and understanding
- Covers applications from simple batch jobs to stream processing and machine learning
- Covers advanced topics like data partitioning and shared variables
Assurance Ubuy
Profitez d'une expérience d'achat sereine avec des produits 100 % originaux, une sécurité de paiement conforme PCI DSS, une protection des données certifiée ISO 27001, la livraison transfrontalière la plus rapide, les retours gratuits* et un emballage sécurisé pour chaque commande.